· Open risks, closed the same evening. Not an incident
Dependencies we couldn't see, and the one inside the checker
This site lists everything that can expire and take it down. Two entries couldn't be read, so the page said so instead of showing them as fine. Closing them turned up a third, inside the checker itself.
Summary
The dependency board on the reliability page lists every credential and registration the site depends on, what breaks if each one lapses, and when it expires, read every day from the service that issued it. On the evening it went live, four entries were green. Two were not: the usage feed's token wasn't set, and the deploy token's expiry had never been reported. The page showed both as risks.
Both were closed within the hour. The fix for the second turned up a third gap: the check for the domain's own expiry depended on a lookup service that refused the site's requests, and my first retry made that worse. By 7:44 p.m. all six entries were green, read from their sources, and the reminders the board had opened had closed themselves.
- Found
- By the board itself: "Unchecked" and "Not recorded", in amber
- User impact
- None. Once read, every entry had at least 329 days left; the risk was not knowing
- Severity
- P3 each: a reminder to the owner, never a page or an incident
- Closed
- 7:43 p.m., 4 October: all six read from their sources, both reminders closed
Why this sits on the reliability page
Objectives answer one question: is the site meeting its targets? They can't answer another: what will stop it while the outside probe is still green? On 2 October the site ran out of its daily database writes. The limit was real and published, but nothing on the page showed it coming. The board is the answer: list what can lapse, read its date, and say plainly when a date can't be read.
Before
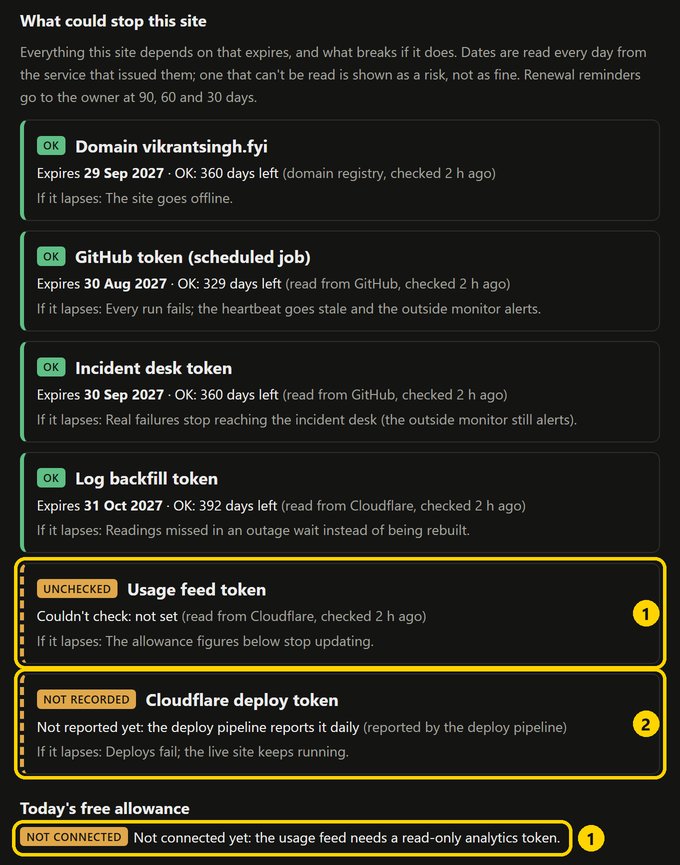
Blast radius
Usage feed missing. Visitors are served and the probe stays green, but I can't see how much of the day's free allowance is used. That's the same class of failure as the write-budget outage: a limit I can't see until it stops something.
Deploy token not reported. A deploy could fail, without warning, on the day the token expires. The live site keeps running either way.
Closing them, and what that found
| 6:20 p.m. | The domain check gets "429: too many requests" from the lookup service |
|---|---|
| 6:28 p.m. | First run of the daily reminder job: the deploy token reads 31 March 2028. Gap 2 closed. It opens P3 reminders for the usage feed and the domain, and both arrive in my inbox |
| 6:36 p.m. | Fix: a retry re-asks only what failed, and a busy service can't erase a good date. My retry had been re-asking every service every 30 minutes, which made the 429 worse |
| 7:00 p.m. | The usage feed token is set and read: 30 November 2027. Today's allowance appears. Gap 1 closed |
| 7:06 p.m. | Fix: ask the .fyi registry directly instead of a shared redirect service |
| 7:40 p.m. | Still 429. Both services limit Cloudflare's shared network addresses, which the site's requests come from |
| 7:42 p.m. | Fix: the daily job, which runs on GitHub's machines, reads the domain's expiry and reports it with the deploy token's |
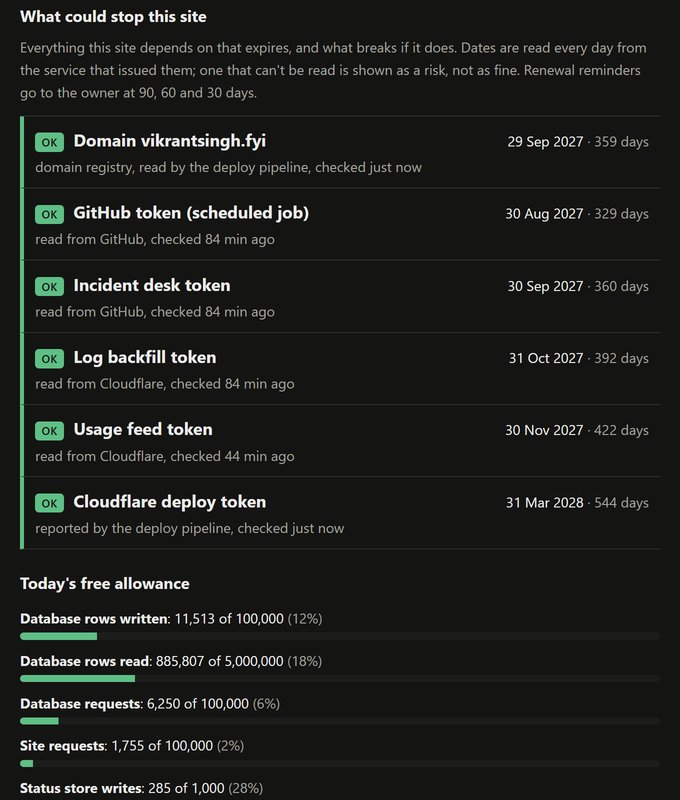
| 7:43 p.m. | All six green. Both reminders closed themselves, and the inbox says so |
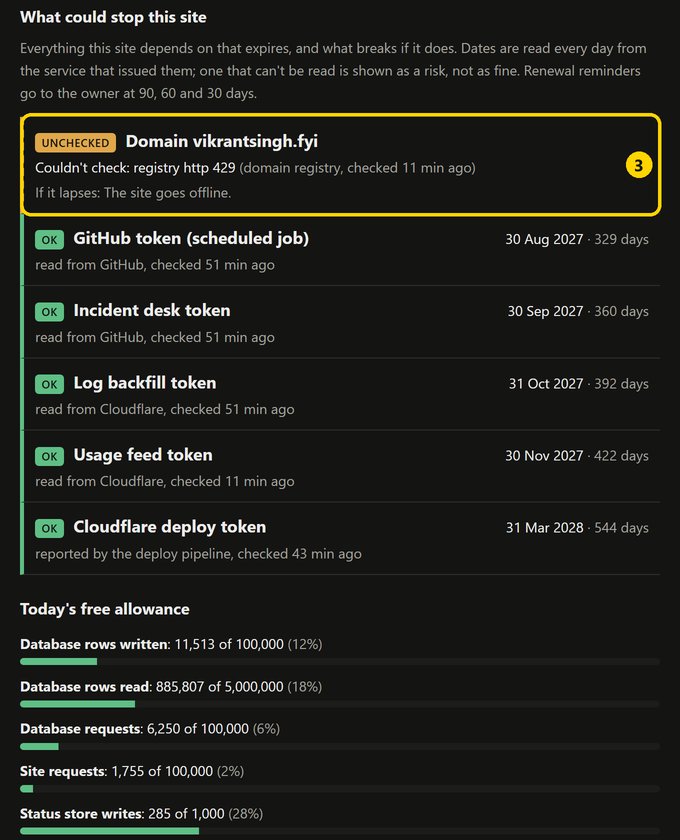
After
The reminders reached a person
A check is only as good as the moment someone reads it, so this is the part I wanted to see. Each reminder is a GitHub issue assigned to me, and GitHub emails it. Both arrived at 6:28 p.m., and the same inbox showed them closing themselves at 7:43 p.m., once the fixes worked. Nobody had to remember to close anything.
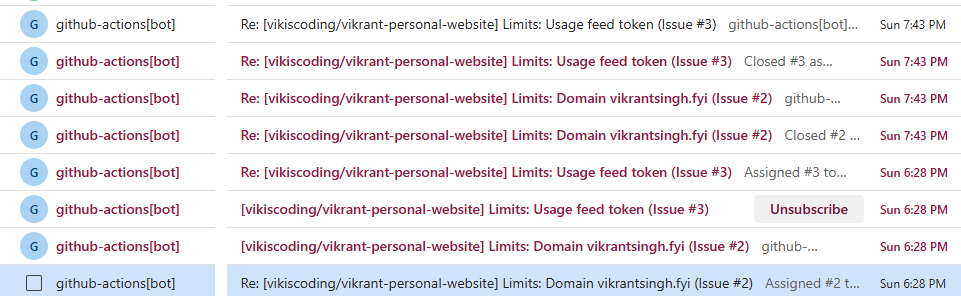
It is noisy: four emails per reminder (opened, assigned, a comment, closed). For a reminder that comes rarely and escalates only as a date nears, that's acceptable. A check that kept reopening would not be.
Findings and actions
| # | Finding | Action | Status |
|---|---|---|---|
| 1 | The usage feed token wasn't set | A read-only analytics token; today's allowance on the page | Done |
| 2 | The deploy token's expiry wasn't reported | The daily job reads it and reports it | Done |
| 3 | The checker depended on a lookup service that refuses the site's network | Read from GitHub's machines by the daily job; the site's own lookup still tried first | Done |
| 4 | My retry asked every service again whenever one failed, and let a busy answer erase a good date | Retry only what failed; keep the last good date through a busy answer | Done |
What this is not
It isn't a configuration database, and it isn't a claim about anyone else's estate. It's one owner-operated site on a free tier, with six things that can expire, run in public.
The rules that came out of it
If the site can't read an expiry or a quota, the page says so. Silence is a bug.
A monitor's own dependencies are dependencies too.
What could stop this site · The failure list that lost its history · Postmortem: the day's database writes · How this site is run